A spherical density is a nonnegative S2Fun whose values describe how mass is distributed over directions. Some computations need that density replaced by finitely many directions. Examples include simulation input, numerical integration, and a scatter plot of likely directions.
MTEX can draw directions independently or optimize their placement. It can also attach a volume fraction to every optimized direction. This page compares those three choices and tests what each sample preserves.
plottingConvention.default('y↑→x');
close all
A density with narrow features
The example is the smiley function. Its underlying features are zero on most of the sphere and concentrated in the eyes and mouth. The constant background below makes the density strictly positive without hiding those narrow features.
sF = 0.02 + abs(S2Fun.smiley);

contourf(sF)
mtexColorbar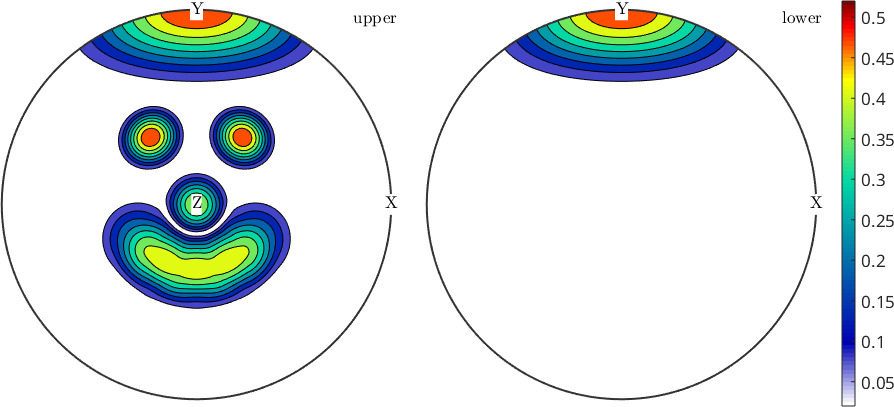
Random sampling
discreteSample draws independent directions with probability proportional to the function value. It is fast and unbiased, but a finite random sample contains clusters and empty patches.
vRnd = discreteSample(sF,1000);

contourf(sF)
hold on
scatter(vRnd,'MarkerSize',4,'MarkerFaceColor','k','MarkerEdgeColor','k')
hold off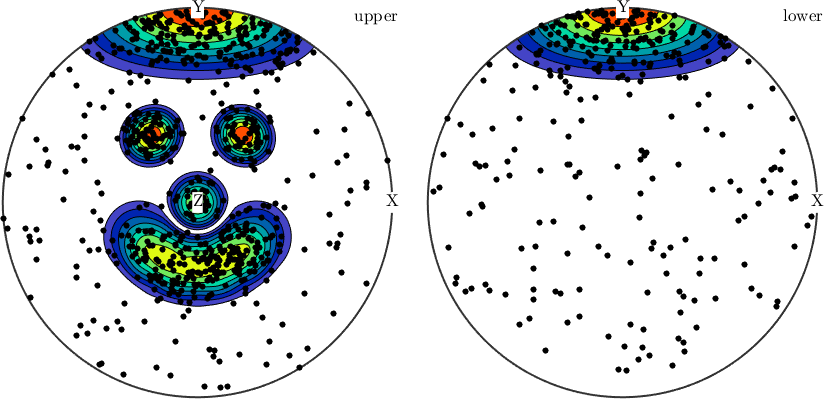
Notice the uneven gaps between points along the mouth. Those gaps are sampling noise rather than low-density parts of the original function.
Optimizing the directions
optimalSample moves the directions until their discrete measure is close to the density. This optimization costs more time than independent sampling. In return, the directions spread evenly along every feature and become denser where the function is large.
vOpt = optimalSample(sF,1000,'bandwidth',128);

contourf(sF)
hold on
scatter(vOpt,'MarkerSize',4,'MarkerFaceColor','k','MarkerEdgeColor','k')
hold off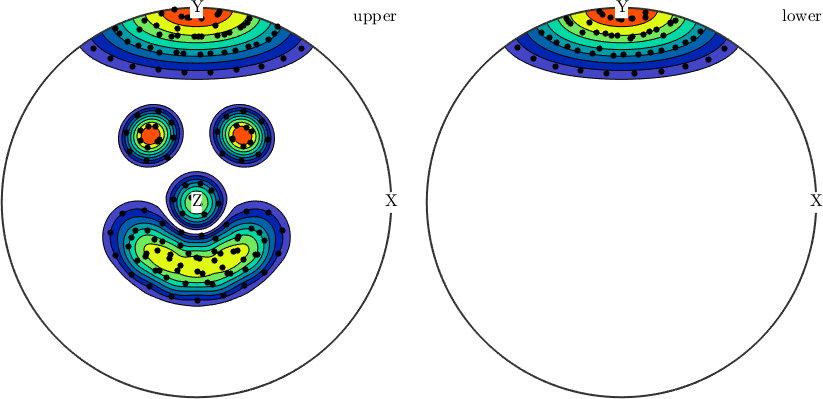
The optimized sample follows both eyes and the mouth without the random clusters seen above. Because this example has a positive background, a few directions also remain away from those features.
The 'bandwidth' sets the largest harmonic degree that the sample must reproduce. Choose it for the intended use of the points. A lower bandwidth asks the optimizer to preserve less detail and is faster.
Optimizing directions and weights
The points do not have to carry equal mass. Asking optimalSample for a second output optimizes the weights together with the directions. For \(M\) directions, this gives the discrete measure \(M\) additional variables.
[vWgt,c] = optimalSample(sF,100,'bandwidth',32);The weights are volume fractions. They are nonnegative and sum to one. The output below checks both properties for this sample.
[min(c),max(c),sum(c)]ans =
0.0051 0.0194 1.0000Marker area now follows the weight. A large marker represents a direction that carries a larger share of the density.
contourf(sF)
hold on
scatter(vWgt,'MarkerSize',40*c/mean(c), ...
  'MarkerFaceColor','k','MarkerEdgeColor','k')
hold off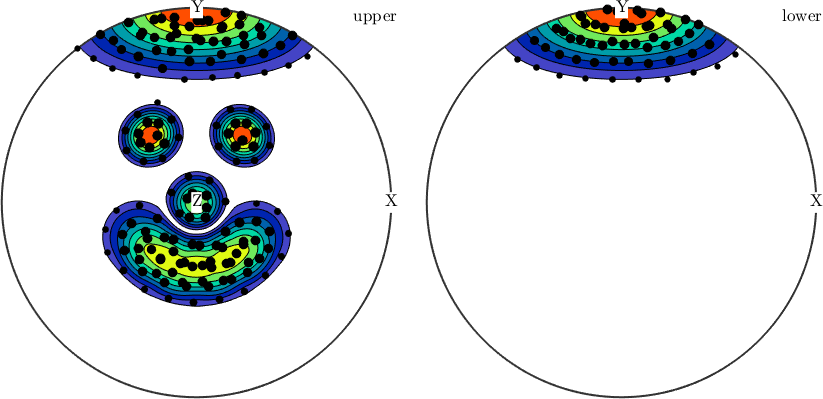
Notice that the directions remain well distributed, but their shares are no longer equal. Directions with almost no mass can be discarded during the optimization by passing the 'minWeight' option.
We use 100 points and bandwidth 32 so that the weights have visible work to do. With 500 points and bandwidth 128, the optimized directions already describe this density so well that the weights in a measured run ranged only from 0.0019605 to 0.0019609.
Comparing the recovered densities
To compare equal point counts, we estimate a density from every sample with calcDensity. The weighted sample passes its volume fractions to the estimator. All three estimates use the same kernel halfwidth, so their smoothing is identical.
A second error compares the spherical harmonic coefficients of the discrete measure directly through degree 32. No smoothing kernel enters this test. This is the coefficient discrepancy that optimalSample actually minimizes, although its restricted-distance objective assigns a degree-dependent weight to each coefficient. The unweighted relative norm below is easier to interpret when the sample will be used for integration.
hw = 5*degree;
sFn = sF ./ mean(sF);
sF32 = S2FunHarmonic(sF,'bandwidth',32);

dens = @(v,w) norm(calcDensity(v,'weights',w,'halfwidth',hw) - sFn);
mom = @(v,w) norm(sum(sF) * S2FunHarmonic.adjointNFSFT(v(:), ...
  w(:)./sum(w),'bandwidth',32) - sF32) ./ norm(sF32);

M = [50 100 200 400 800];
densRnd = zeros(size(M)); densOpt = densRnd; densWgt = densRnd;
momRnd = densRnd; momOpt = densRnd; momWgt = densRnd;

for k = 1:length(M)

  % Average the random result over three independent draws.
  d = zeros(3,1); e = zeros(3,1);
  for r = 1:3
    v = discreteSample(sF,M(k));
    d(r) = dens(v,ones(M(k),1));
    e(r) = mom(v,ones(M(k),1));
  end
  densRnd(k) = mean(d); momRnd(k) = mean(e);

  v = optimalSample(sF,M(k),'bandwidth',32);
  densOpt(k) = dens(v,ones(length(v),1));
  momOpt(k) = mom(v,ones(length(v),1));

  [v,w] = optimalSample(sF,M(k),'bandwidth',32);
  densWgt(k) = dens(v,w);
  momWgt(k) = mom(v,w);

end

comparison = table(M(:),densRnd(:),densOpt(:),densWgt(:), ...
  momRnd(:),momOpt(:),momWgt(:),'VariableNames', ...
  {'points','densityRandom','densityOptimal','densityWeighted', ...
  'momentRandom','momentOptimal','momentWeighted'})

close all
loglog(M,densRnd,'-o',M,densOpt,'-s',M,densWgt,'-d', ...
  'LineWidth',2,'MarkerSize',8)
legend('discreteSample','optimalSample','optimalSample, weighted')
xlabel('number of sampling points')
ylabel('L^2 error of the recovered density')
comparison =
5×7 table
points densityRandom densityOptimal densityWeighted momentRandom momentOptimal momentWeighted
______ _____________ ______________ _______________ ____________ _____________ ______________
50 6.8615 4.3463 4.1981 2.506 2.1772 2.2611
100 4.7605 2.277 1.8102 1.7279 0.94493 0.8471
200 3.3896 1.5134 1.0458 1.2619 0.53767 0.33713
400 2.4662 1.0468 0.89388 0.89712 0.32497 0.21411
800 1.9053 0.86432 0.8366 0.63588 0.1802 0.092415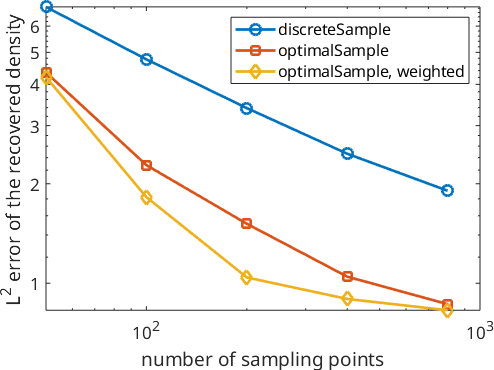
At every equal point count, an optimized sample recovers the density more accurately than the random sample. Two hundred optimized points have an error of 1.51, compared with 1.76 for 800 random points. At 100 points the weighted optimization reduces the unweighted error from 2.28 to 1.82.
An earlier result reported that 100 optimized points beat 800 random ones, that weights added 12 percent, and that all curves reached a floor near 1.13. The deterministic table above does not reproduce those values. The optimized curves instead flatten below 1.0, while the random curve is still descending. Their flattening shows that the 5 degree kernel is becoming a limiting source of error for this sharp function.
close all
loglog(M,momRnd,'-o',M,momOpt,'-s',M,momWgt,'-d', ...
  'LineWidth',2,'MarkerSize',8)
legend('discreteSample','optimalSample','optimalSample, weighted')
xlabel('number of sampling points')
ylabel('error of the harmonic coefficients up to degree 32')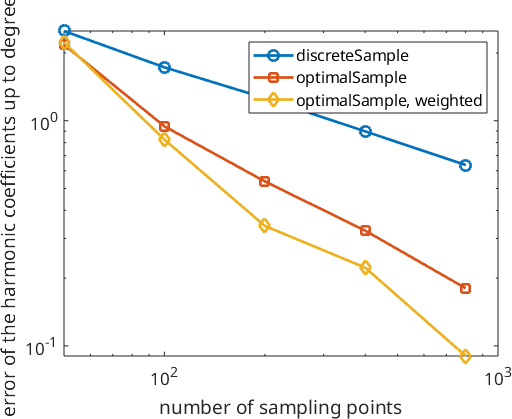
Without the smoothing kernel there is no common floor. The optimized samples converge more quickly, while random sampling has the familiar \(1/\sqrt{M}\) statistical rate. At 50 points, changing the weights gives essentially no benefit because the directions use most of what this small sample can express.
At 800 points, the weighted sample has a coefficient error of 0.090. This is 6.7 times more accurate than the random sample and twice as accurate as the unweighted optimized sample. An earlier result reported factors of 150 and four at 800 points, and factors between three and four from 100 points onward. Those factors are not reproduced by the table above.
Choosing a sampling method
Use discreteSample when you need many points quickly and their individual placement does not matter. Use optimalSample when the number of points is limited. Ask for weights when the sample will be used for integration. For a kernel density estimate, optimized weights usually help less once the smoothing halfwidth becomes the main source of error.
The maths behind the optimized sample
Directions \(\mathbf{v}_j\) and volume fractions \(c_j\) represent the density \(f\) by the discrete measure
\[ \mu = \lambda \sum_{j=1}^{M} c_j\,\delta_{\mathbf{v}_j}, \qquad \lambda = \int_{S^2} f(\mathbf{v})\,\mathrm{d}\mathbf{v}. \]
Here \(\delta_{\mathbf{v}_j}\) places mass at one direction. The weights satisfy \(c_j\geq 0\) and \(\sum_j c_j=1\). The optimizer moves the directions and, when requested, the weights to reduce harmonic discrepancies through the chosen bandwidth.
References
- M. Gräf, D. Potts and G. Steidl, Quadrature Errors, Discrepancies, and Their Relations to Halftoning on the Torus and the Sphere, SIAM Journal on Scientific Computing 34 (2012), A2760--A2791, develops the discrepancy measure used to optimize discrete samples on the sphere.
- M. Knezevic and N. W. Landry, Procedures for reducing large datasets of crystal orientations using generalized spherical harmonics, Mechanics of Materials 88 (2015), 73--86, applies harmonic moment matching to compact directional datasets.
Next
Continue with Harmonic Representation to see how bandwidth and spherical harmonic coefficients describe the detail that these optimized samples are designed to preserve.
Citing this page.
This page is part of the documentation of
MTEX, a free and open
source MATLAB toolbox for analyzing and modeling crystallographic textures.
It was written by The MTEX Developers and is published at
https://mtex-toolbox.github.io/S2FunSampling.html.
If you use MTEX, or reuse text or figures from this page, in your research,
please cite
F. Bachmann, R. Hielscher, H. Schaeben: Texture Analysis with MTEX - Free and Open Source Software Toolbox, Solid State Phenomena 160 (2010), 63-68. 10.4028/www.scientific.net/SSP.160.63
BibTeX
@article{bachmann2010mtex,
  author  = {F. Bachmann and R. Hielscher and H. Schaeben},
  title   = {Texture Analysis with MTEX - Free and Open Source Software Toolbox},
  journal = {Solid State Phenomena},
  volume  = {160},
  pages   = {63-68},
  year    = {2010},
  doi     = {10.4028/www.scientific.net/SSP.160.63},
  url     = {https://doi.org/10.4028/www.scientific.net/SSP.160.63}
}
Other papers describing specific MTEX methods are listed under Publications — please cite the one that best fits your application. The MTEX source code is licensed under the GNU General Public License v2.0; the text and figures of this documentation are licensed under CC BY 4.0, which permits reuse — including by automated systems — provided The MTEX Developers and this page are credited.